- AI
- Software Architecture
- Engineering
Where Should AI Stop and Ordinary Code Begin?
A practical way to decide which parts of a system need AI judgment and which parts should remain predictable, testable code.
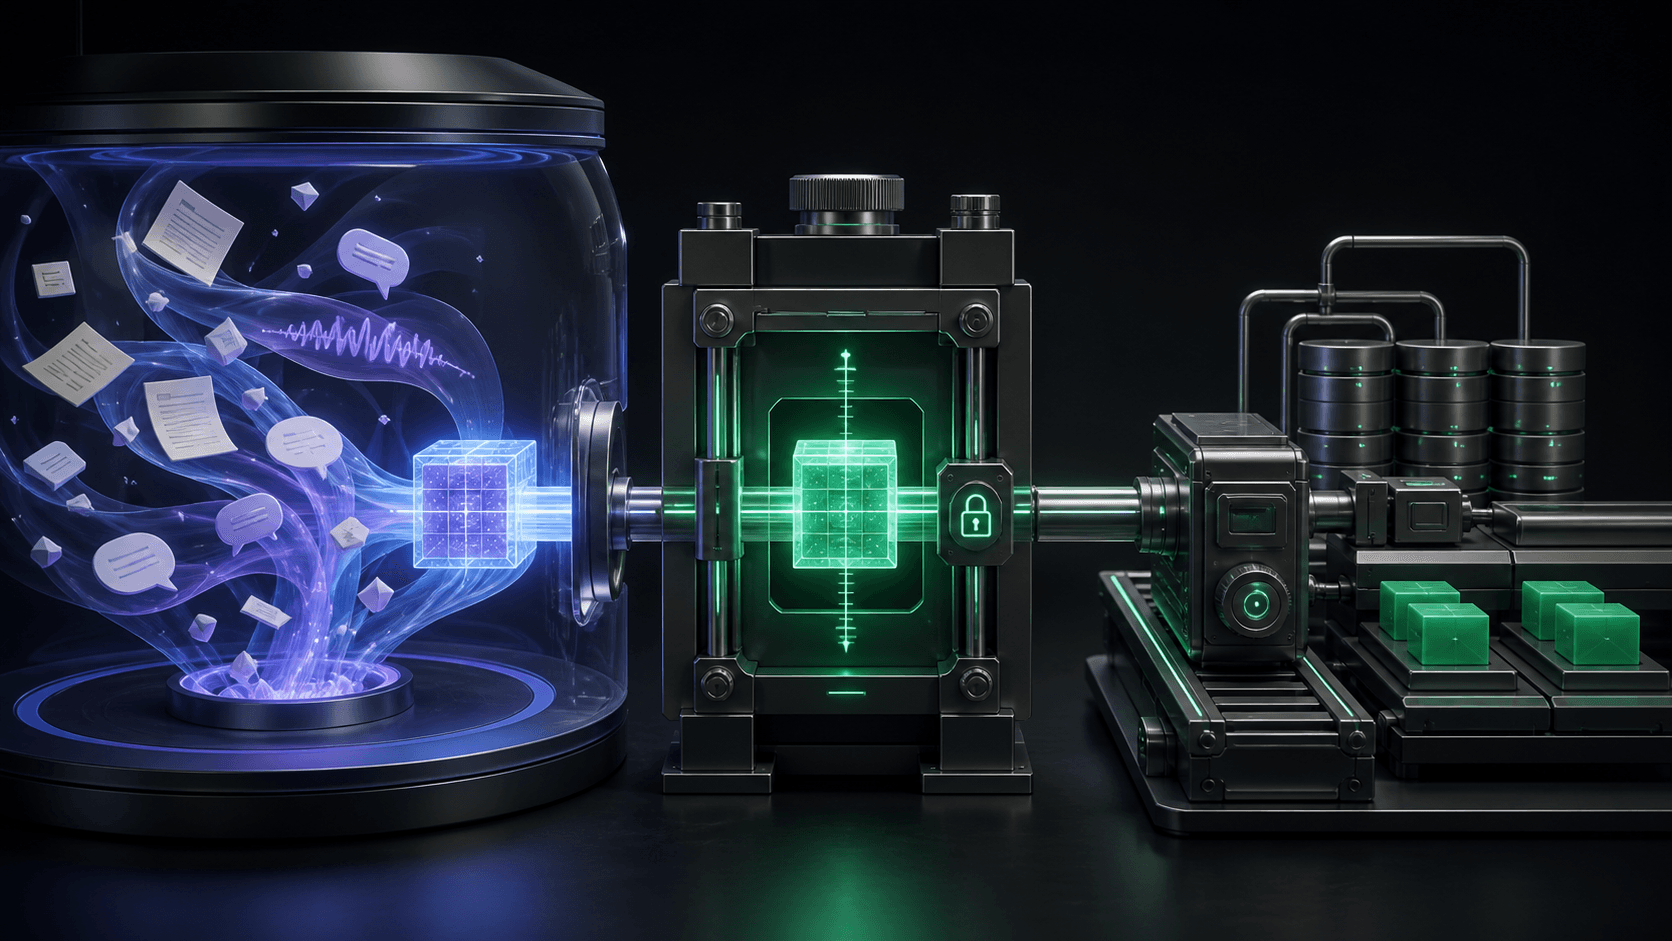
AI can summarize documents, write emails, generate code, and make surprisingly useful suggestions.
That makes it tempting to give AI an entire task and say, “You understand what I want. Just handle everything.”
I tried something close to that.
It worked often enough to make me confident—and failed often enough to make me nervous.
The problem was not that the AI was useless. I had given it two very different responsibilities: making judgments and following exact rules.
Imagine asking AI to read a customer complaint and decide whether the customer sounds unhappy. That is a reasonable use of AI because language can be ambiguous.
Now imagine asking the same AI to calculate the exact refund, transfer the money, and update the customer’s balance. Suddenly, “probably correct” is not good enough.
That is the boundary I had to learn:
AI is useful when a task requires interpretation. Ordinary code is better when the result must be guaranteed.
What Do I Mean by “Ordinary Code”?
By ordinary code, I mean the predictable instructions developers have always written.
If a customer has a balance of $100 and receives a $20 refund, ordinary code calculates the new balance as $120. It does not reconsider the meaning of addition, choose a more creative number, or have a particularly imaginative Tuesday.
Given the same input and the same rules, it produces the same result.
AI works differently. It is good at dealing with information that is unclear, inconsistent, or written in natural language. It can make a useful judgment even when there is no perfect rule for every situation.
Neither approach is automatically better. They solve different kinds of problems.
Give AI Tasks That Require Judgment
AI is most useful when the input cannot be described with a small set of exact rules.
For example, AI can help with:
- summarizing a long document
- identifying the intention behind a message
- extracting information from inconsistent text
- categorizing support requests
- finding patterns across different document layouts
- suggesting possible answers or next steps
Consider a support email that says:
“I have tried this three times, and it still does not work. I need this resolved today.”
The customer never writes, “My emotional state is angry.” A traditional program would need rules based on specific words or phrases. AI can interpret the overall message and recognize urgency or frustration.
That is judgment. There may not be one mathematically perfect answer, but a useful interpretation is possible.
Give Code Tasks That Require Guarantees
Some parts of a system cannot be “mostly right.”
Ordinary code should usually control tasks such as:
- calculating prices, totals, or refunds
- checking permissions
- preventing duplicate bookings
- validating required information
- saving records to a database
- enforcing business rules
- transforming data into an exact format
- sending or recording payments
If two venue owners attempt to book the same singer for the same time, the platform needs a clear rule. It should not ask AI which booking “feels more correct.”
The database and application code should enforce availability consistently.
The same principle applies to permissions. AI might help explain why a user cannot access something, but it should not casually decide whether that user is an administrator.
A Document-Processing Example
Document processing makes this boundary easy to see. A workflow may need AI to interpret varied language or layouts, while the resulting data still has to follow a strict structure.
In a document workflow I worked on, putting every possible rule and example into one prompt made the results less consistent. The system had too much context and too many responsibilities. Sometimes it applied the relevant rule; sometimes it mixed cases together or returned information that looked plausible but failed validation.
The better approach was to give the AI only the context relevant to the document at hand, then let ordinary code validate required fields and produce the exact output format.
AI handled interpretation. Code handled guarantees.
I explore this design lesson in From Complex Documents to Reliable Data. The same boundary applies far beyond document processing.
AI Can Assist Without Being in Control
The choice is not always between “use AI” and “do not use AI.”
AI can participate in a process without having final authority over it.
For example:
- AI extracts fields; code verifies that required fields are present.
- AI recommends a category; a person approves sensitive cases.
- AI drafts a reply; the user decides whether to send it.
- AI identifies a possible duplicate; code checks exact identifiers.
- AI suggests a booking option; code confirms actual availability.
This is often more useful than trying to automate the entire decision.
An AI assistant does not need permission to press every button just because it helped find the button.
Five Questions I Ask Now
When deciding whether a responsibility belongs to AI or ordinary code, I ask five questions.
1. Must the same input always produce the same result?
If yes, ordinary code is usually the safer choice.
A tax calculation, access check, or booking conflict should not change because the model responded differently today.
2. Can I describe the rule exactly?
If the rule can be written clearly as conditions, calculations, or validation steps, it probably does not need AI.
“A booking cannot overlap another confirmed booking” is an exact rule. Code can enforce it.
“Does this message sound urgent?” requires interpretation. AI may help.
3. What happens when the answer is wrong?
The consequences matter.
If an incorrect summary causes a small inconvenience, AI output may be acceptable with a disclaimer. If an incorrect result sends money, exposes private information, or creates a legal document, validation and human review become much more important.
4. Can the result be validated?
AI becomes safer when its output passes through checks.
Can the system verify the format? Can it confirm required fields? Can it reject impossible values? Can a person review uncertain cases?
If there is no way to detect a wrong answer, the AI may have too much responsibility.
5. Is AI adding real value here?
Sometimes developers use AI because it is available, not because the task needs it.
If ten lines of code can solve the problem reliably, adding a model may introduce cost, latency, and new failure cases without providing a meaningful benefit.
Not every problem becomes smarter after an AI API call.
A Simple Decision Framework
The boundary can be summarized like this:
- Inconsistent or natural-language input: Start with AI.
- Interpretation or judgment: Start with AI.
- The same input must always produce the same output: Use ordinary code.
- A rule can be expressed exactly: Use ordinary code.
- A mistake affects money, access, or critical data: Use code, validation, and possibly human review.
- AI produces a result that can be checked: Combine AI with ordinary code.
This is not a perfect formula. It is a starting point for designing the responsibilities clearly.
The Boundary Is Part of the Product
Users do not care which part of a system uses AI. They care whether the system is useful, understandable, and reliable.
Sometimes the best AI feature is the one surrounded by ordinary code that catches its mistakes.
The goal is not to maximize how much AI a product uses. The goal is to use AI where it creates value without giving up the guarantees the product needs.
My first approach tried to make the AI responsible for the entire result. The better approach gave it a smaller, clearer job and allowed ordinary code to protect everything that had to be exact.
That is the boundary I use now:
Let AI make the judgment. Let code enforce the promise.
How did this land?
A tiny signal is enough—no account needed.